Prompt-driven scenes
Specify objects, relationships and the intended visual atmosphere.
Create images with the fine-tuned MOSS Image SFT model. Explore visual directions for posters, editorial concepts and creative work from a text prompt.
Your finished audio, image or text will appear here.
Create images with the SFT variant of the MOSS-Image family. The official project offers Base and SFT checkpoints for text-to-image generation, including bilingual text rendering and varied visual styles. Use the SFT workspace to test a detailed creative direction with a chosen canvas shape. Keep the prompt specific: explain what should appear, how it should be arranged and the mood the image should convey.
Specify objects, relationships and the intended visual atmosphere.
Explore image concepts involving English or Chinese text.
Try the same brief with Base to understand the difference in your results.
Official examples are credited to OpenMOSS. Studio samples were generated by us with the named API model. These are saved previews, not a result of your current settings. Research capabilities and available studio controls may differ.
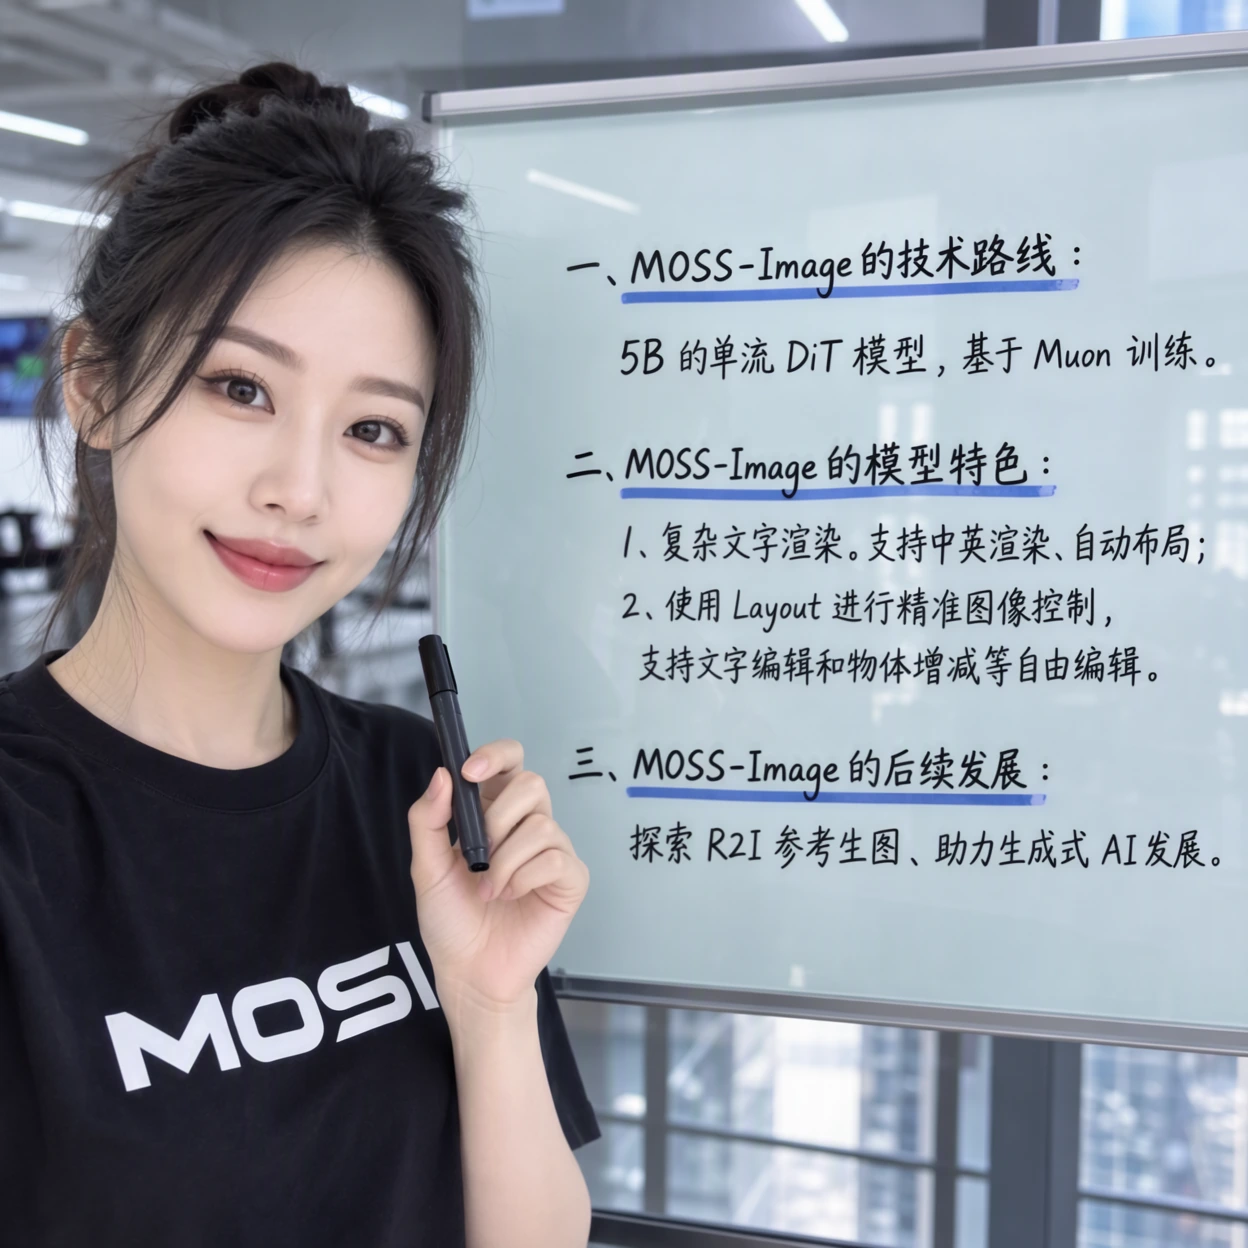
Develop a hero-image direction or a product storytelling scene.
Explore a defined art direction before selecting the final composition.
6 credits per generated image, regardless of which preset canvas shape you select.
No. Results depend on your prompt and task. Compare actual images instead of assuming one variant always wins.
This workspace currently supports text-to-image generation. Image-to-image editing is not available.
Choose a model, add your input and review the credit cost. Successful results stay in your account history; AI output may be inaccurate.
Text is rounded up to a whole credit. Audio is billed per started minute. Live voice uses one credit per 6 seconds.
Result links can expire. Download files you want to keep.
Model documentation